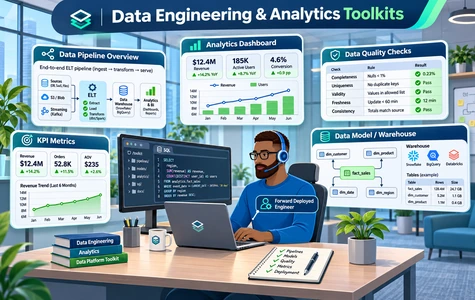
Reliable business intelligence starts with dependable data models and pipelines. The Data Engineering & Analytics Toolkits bring together practical engineering guides, worksheets, diagrams, executable exercises and test datasets for designing, operating and validating enterprise data solutions.
Across 6 focused parts and 40 indexed files, the toolkit covers relational and dimensional database modeling; batch ETL/ELT and incremental loading; pipeline observability, restart and replay; event-time streaming and watermarking; data quality rules, contracts and lineage; and semantic-layer design with BI metric reconciliation.
Designed for data engineers, analytics engineers, database architects, platform teams, BI leads and Forward Deployed Engineers, the resources support SQL and Python-based exercises, structured technical reviews and consistent data validation practices. DOC, XLS, Draw.io, SQL, Python, CSV, JSON and JSONL materials can be adapted to your technology stack and enterprise use cases.
- Design trustworthy data models with relational schema guidance, SQL labs, key-validation exercises and dimensional ER diagrams.
- Engineer repeatable ETL/ELT workflows using transformation rules, incremental-load models, batch test records and a Python reference implementation.
- Improve pipeline resilience with freshness and volume monitoring, alert thresholds, replay tests, restart runbooks and failure-event fixtures.
- Handle real-time and late-arriving events through windowing, watermark calculations, streaming processor exercises and event-quality reviews.
- Strengthen data quality and analytics consistency with data contracts, lineage verification, semantic metric definitions and BI reconciliation checks.
Below is the complete file inventory from Index 09: 40 files organized across 6 parts, including Word and Excel templates, Draw.io diagrams, SQL and Python labs, and CSV/JSON/JSONL fixtures.
| Type | Files List |
|---|---|
| Relational_Database_Design_Playbook.doc | |
| Data_Model_Conformance_Checklist.xls | |
| Data_Model_Review_Rubric.xls | |
| Dimensional_Entity_Relationship_Model.drawio | |
| Schema_Design_SQL_Lab.sql | |
| Primary_Foreign_Key_Validation_Exercise.sql | |
| ETL_ELT_Pipeline_Design_Specification.doc | |
| Source_Target_Transformation_Rules.xls | |
| Incremental_Load_State_Model.xls | |
| Pipeline_Batch_Test_Results.xls | |
| Batch_ETL_Reference_Implementation.py | |
| Batch_Source_Transactional_Data.csv | |
| ETL_Failure_Recovery_Exercise.doc | |
| Data_Pipeline_Reprocessing_and_Restart_Runbook.doc | |
| Data_Pipeline_Freshness_Volume_Observability.xls | |
| Data_Pipeline_Alert_Threshold_Matrix.xls | |
| Pipeline_Replay_Idempotency_and_Duplicate_Handling_Test_Cases.xls | |
| Pipeline_Recovery_and_Replay_Lab.py | |
| Pipeline_Failure_Event_Fixtures.jsonl | |
| Real_Time_Event_Processing_Guide.doc | |
| Out_Of_Order_Event_Exercise.doc | |
| Window_and_Watermark_Calculator.xls | |
| Streaming_Event_Quality_Review.xls | |
| Event_Time_Stream_Processor.py | |
| Streaming_Recovery_Lab.py | |
| Streaming_Event_Fixtures.jsonl | |
| Data_Quality_Incident_Casebook.doc | |
| Data_Contract_Breaking_Change_Approval_Record.doc | |
| Data_Quality_Rule_Catalog.xls | |
| Data_Lineage_Verification_Checklist.xls | |
| Data_Lineage_Diagram.drawio | |
| Data_Quality_Control_Test_Lab.py | |
| Data_Contract_Definition.json | |
| Analytics_Semantic_Layer_Design_Guide.doc | |
| Analytical_Insight_Validation_Cases.doc | |
| Semantic_Metric_Definition_Catalog.xls | |
| BI_Metric_Reconciliation.xls | |
| Analytics_Definition_Review_Checklist.xls | |
| Analytics_Mart_SQL_Model.sql | |
| Analytics_Test_Dataset.csv | |
Price: $47.00

Secure payment via PayPal. Instant digital delivery after successful payment.
| Date File Updated | 10/04/2025 |
|---|---|
| File Format | doc, xls, sql, drawio, py, csv, jsonl, json |
| No. of files | 40 Files, 6 Folders |
| File download size | 3.02 MB (.rar) |
| Language | English |
This document has been certified by a professional
100% customizable. You can edit our templates as needed.
Instant download after completing your order.
We recommend downloading this file onto your computer.
Your payment information is processed securely.
After payment, if you require an invoice, please email us.
Support contact: supports@it-toolkits.org
Build reliable data pipelines and trusted analytics
Practical resources for data modeling, ETL/ELT transformation, pipeline recovery, real-time streaming, data contracts, lineage assurance, semantic metrics and BI reconciliation.
1. Who is the Data Engineering & Analytics Toolkit designed for?
The toolkit is designed for Forward Deployed Engineers, data engineers, analytics engineers, database architects, BI leads, data platform teams and technical delivery managers who design, validate or maintain enterprise data workflows.
2. What topics does the toolkit cover?
Index 09 organizes the resources into 6 parts: data models and schemas; batch ETL/ELT; pipeline observability and replay; real-time streaming; data quality and lineage; and analytics engineering with metric reconciliation.
3. How many files and formats are included?
The supplied index lists 40 files across 6 parts: 10 DOC, 15 XLS, 5 PY, 3 SQL, 2 DRAWIO, 2 CSV, 2 JSONL and 1 JSON file. The full inventory appears above.
4. Can I review all filenames before purchasing?
Yes. The Toolkit Documents section lists the precise filenames from Index 09 in source order. The existing Download Index and Payment Guide buttons are maintained below the pricing card.
5. Does the toolkit include relational and dimensional database design?
Yes. Part 1 contains a relational database design playbook, model conformance and review checklists, a dimensional entity-relationship diagram, and SQL exercises for schema design and primary/foreign-key validation.
6. How can the toolkit support batch ETL/ELT implementation?
Part 2 contains an ETL/ELT pipeline design specification, source-to-target transformation rules, incremental-load state modeling, batch test results, a Python reference implementation and transactional CSV sample data.
7. Does it cover data pipeline monitoring and alerting?
Yes. Part 3 contains freshness and volume observability worksheets and an alert-threshold matrix. These resources help teams define measurable expectations and investigate pipeline failures.
8. How are restart, recovery and replay scenarios handled?
Part 3 includes a reprocessing and restart runbook, an ETL failure recovery exercise, test cases for replay, idempotency and duplicate handling, plus a Python replay lab and JSONL failure fixtures.
9. Does the toolkit support streaming and event-time processing?
Yes. Part 4 covers real-time event processing, out-of-order events, window and watermark calculation, event-quality review, Python stream-processing and recovery exercises, and JSONL event fixtures.
10. What data quality and data contract resources are included?
Part 5 includes data-quality incident cases, a breaking-change approval record, a rule catalog, a data-lineage verification checklist, a lineage diagram, a Python control test lab and a JSON data-contract definition.
11. Can the toolkit help verify data lineage and dependencies?
Yes. Part 5 includes a Data Lineage Diagram in Draw.io format and a Data Lineage Verification Checklist for reviewing transformations, dependencies and traceability.
12. Does it support semantic models and consistent BI metrics?
Part 6 offers semantic-layer design guidance, metric definition catalogues, BI metric reconciliation worksheets, analytics definition review, SQL mart modeling and an analytics test dataset.
13. Are there executable SQL and Python learning exercises?
Yes. The index explicitly includes 3 SQL files and 5 Python files for database keys, ETL, replay, streaming, data quality controls and analytics modeling. Execution requirements depend on your local environment.
14. Are sample data and event fixtures provided?
The index includes 2 CSV files, 2 JSONL files and 1 JSON file for transactional batch data, streaming/failure events, data contracts and analytics test cases. Review these illustrative datasets before applying them to production.
15. Can these materials be customized for our technology platform?
The DOC, XLS and Draw.io materials can be tailored to internal conventions; the SQL and Python exercises can be adapted to compatible databases and runtimes. Teams should review dependencies, access controls and data governance requirements first.
16. Can the toolkit be used as-is in a production environment?
The resources are intended to support design, exercises, technical review and adaptation. Before production use, validate the code and datasets, implement security controls, perform testing and obtain appropriate operational approvals.
17. What is the price and how does payment work?
The listed price is $47.00 USD. The page preserves the PayPal checkout forms from the website template and the existing Payment Guide. The product-specific PayPal configuration should be confirmed before the page goes live.
18. Where can I get support or help with these file formats?
For document access or questions about adapting the toolkit, email supports@it-toolkits.org. SQL and Python require suitable development tools, and Draw.io files require a compatible diagram editor.
Enterprise Systems & OT/IT Integration Toolkits
Connect enterprise data flows across APIs, ERP/CRM systems and controlled industrial interfaces.
AI, LLM & Agent Solution Engineering Toolkits
Build dependable data foundations and test inputs for AI, LLM and agent-based applications.
Solution Architecture & Technical Design Toolkits
Align data platforms, system boundaries and architecture decisions with enterprise delivery.
Cloud, Hybrid & Edge Platform Engineering Toolkits
Extend data pipelines onto the cloud and edge infrastructure that hosts their workloads.
Software & Application Engineering Toolkits
Apply coding, debugging, testing and application engineering practices to data services.
Business Case, ROI & Value Realization Toolkits
Connect reliable BI metrics to measurable benefits, ROI baselines and value realization.


English